For years, the AI industry depended heavily on one basic formula:
Build better AI models → buy more GPUs → build larger data centers.
That formula is changing.
Companies developing and operating large AI systems are increasingly designing their own processors and accelerators.
Google has its Tensor Processing Units (TPUs). Amazon has Trainium. Microsoft has Maia. Meta has MTIA. OpenAI has also entered custom accelerator development through its partnership with Broadcom.
The reason is not simply that these companies want to become semiconductor companies.
The bigger reason is economics.
Running modern AI at massive scale requires enormous amounts of computing power, memory bandwidth, networking capacity and electricity. A chip designed specifically around a company’s AI workloads can potentially reduce wasted resources and improve performance per dollar and per watt.
This is especially important as AI moves from occasional chatbot requests toward continuous inference, coding agents, enterprise workloads and autonomous systems.
The question is therefore no longer just:
Who makes the fastest AI chip?
It is increasingly:
Can an AI company design the right chip for the workloads it actually runs?
Why GPUs Became the Foundation of AI
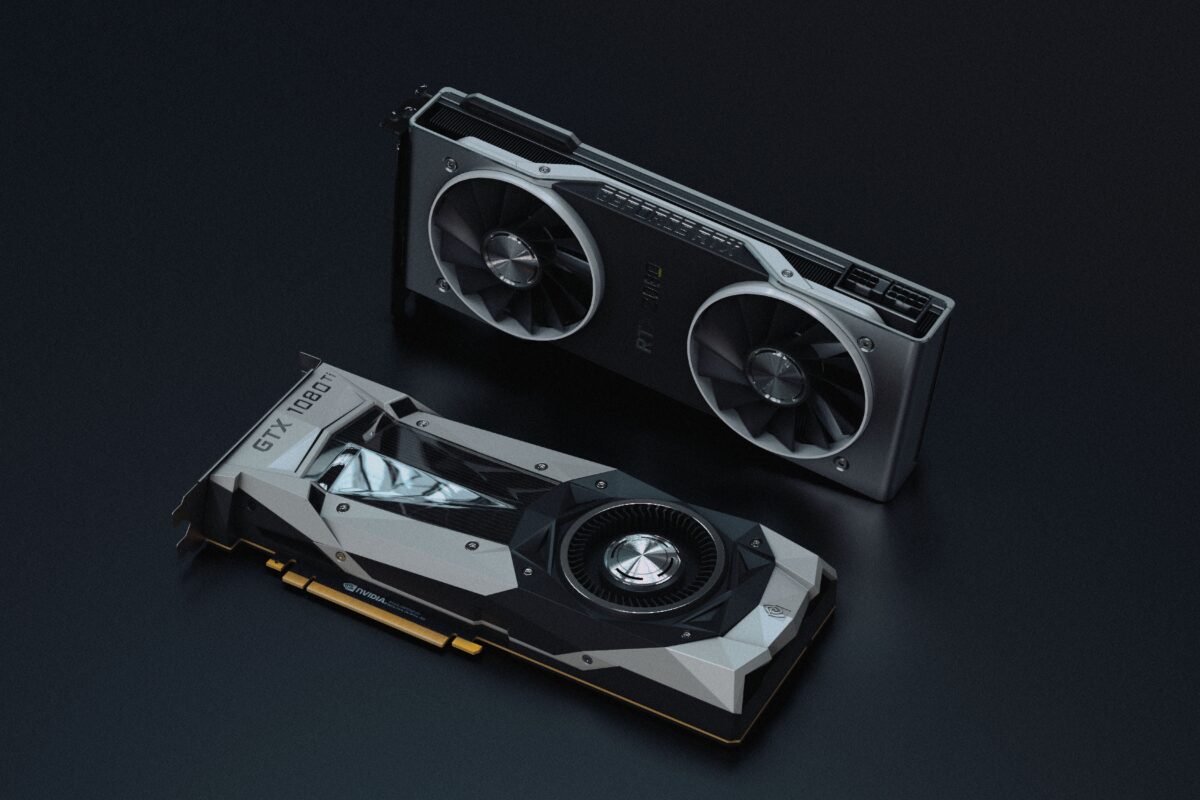
Before looking at custom chips, it is important to understand why GPUs became so important in the first place.
AI models perform enormous numbers of mathematical operations, particularly matrix and tensor operations.
GPUs are extremely good at performing many calculations in parallel.
A simplified comparison looks like this:
CPU

Few powerful cores
       ↓
General-purpose workloads


GPU

Many parallel processing units
       ↓
Massive mathematical workloads
       ↓
AI training and inference
Modern AI workloads can therefore use thousands of accelerators simultaneously.
Our article on why NVIDIA GPUs are important for AI explains how GPUs became central to modern AI computing.
But GPUs are general-purpose accelerators.
They can support many different workloads, which is one reason they are so valuable.
The problem is that an AI company running a very specific workload may not need everything a general-purpose GPU provides.
That creates an opportunity for specialization.
What Is a Custom AI Chip?
A custom AI chip is a processor or accelerator designed specifically around particular workloads.
Instead of starting with:
General-purpose hardware
        ↓
Adapt software to hardware
the design process can look more like:
AI workload
    ↓
Model architecture
    ↓
Software / kernels
    ↓
Memory requirements
    ↓
Networking requirements
    ↓
Custom accelerator
The chip can then be optimized around the actual behavior of the AI systems it needs to run.
For example, a company may know that its workloads require:
- enormous matrix computation
- large amounts of HBM
- high memory bandwidth
- low-latency networking
- specific numerical formats
- high inference throughput
- efficient data movement
- predictable workloads
The chip can be designed around those requirements.
That is the fundamental idea behind custom AI silicon.
The AI Industry Is Moving From Training to Inference
One of the biggest reasons custom chips are becoming important is the changing balance between training and inference.
Training is the process of teaching a model using enormous datasets and compute resources.
Inference happens when the trained model actually generates an answer.
For example:
Training

Data
 ↓
AI model
 ↓
Millions / billions of calculations
 ↓
Trained model
Then:
Inference

User request
 ↓
Trained model
 ↓
AI computation
 ↓
Response
As AI applications become widely used, inference can become an enormous continuous workload.
Every ChatGPT response, coding request, AI search query, image generation request or agent action requires computation.
Our guide to AI inference and how AI models generate responses explains this process in more detail.
This is one reason several custom-chip programs are explicitly focusing on inference.
OpenAI Is Building Custom AI Silicon
OpenAI is one of the newest major AI companies to move further into custom accelerator development.
In June 2026, OpenAI and Broadcom announced Jalapeño, an accelerator designed specifically around large language model inference.
OpenAI’s announcement of the Jalapeño AI accelerator
OpenAI says the chip was designed from scratch around its understanding of LLMs, including model kernels, memory movement, networking and serving requirements.
The important part is not simply that OpenAI has a chip.
It is that OpenAI is attempting to optimize more of the stack together:
AI models
    ↓
Kernels
    ↓
Chip architecture
    ↓
Memory
    ↓
Networking
    ↓
Servers
    ↓
Data centers
    ↓
AI products
OpenAI says Jalapeño is intended for deployment at gigawatt scale with data-center partners across multiple generations.
The company also says early testing indicates substantially better performance per watt than the current state of the art, although it notes that final performance measurements were still being evaluated when the announcement was made.
That distinction matters.
A custom chip does not automatically become better than every GPU.
The goal is to make the company’s own workloads more efficient.
Google Has Been Building AI Chips for More Than a Decade
Google is not new to custom AI hardware.
Its Tensor Processing Unit, or TPU, has been developed specifically for machine-learning workloads for years.
Google’s TPU strategy has evolved alongside its AI models.
The company’s seventh-generation Ironwood TPU was designed specifically with inference in mind. Google describes it as a custom accelerator for the “age of inference.”
Google’s Ironwood TPU announcement
Google reported that Ironwood can scale to 9,216 liquid-cooled chips and that its performance-per-watt was designed to improve substantially over the previous generation.
Google then introduced two specialized TPU designs in 2026:
- TPU 8i, focused on inference and agentic workloads
- TPU 8t, focused on training
Google Cloud’s TPU 8 announcement
This illustrates an important concept.
Google is not trying to build one chip that does everything.
It is developing different hardware around different AI workloads.
Amazon Uses Trainium for AI Workloads
Amazon has also invested heavily in custom silicon.
Its AI accelerator family includes Trainium, which is designed for AI training and inference.
Amazon describes its custom silicon strategy as covering both AI and general-purpose cloud computing, with Trainium aimed at AI workloads and Graviton aimed at general-purpose compute.
Amazon’s custom silicon overview
The advantage for Amazon is particularly interesting because AWS operates one of the world’s largest cloud platforms.
AWS does not simply need chips for one internal AI product.
It can deploy custom silicon across its cloud infrastructure and make that infrastructure available to customers.
The basic strategy becomes:
Amazon designs chip
        ↓
AWS deploys chip
        ↓
Cloud customers use chip
        ↓
More workloads
        ↓
Amazon improves next generation
That gives custom silicon a broader economic purpose.
It becomes part of the cloud business itself.
Microsoft Has Maia for AI Inference
Microsoft is following a similar path with its Maia family of AI accelerators.
In January 2026, Microsoft introduced Maia 200, an inference-focused accelerator built on TSMC’s 3nm process.
Microsoft’s Maia 200 announcement
Microsoft says Maia 200 contains more than 140 billion transistors and includes 216 GB of HBM3e with 7 TB/s of memory bandwidth.
The company designed it around large-scale AI inference and integrated it into Azure infrastructure.
The interesting part is that Microsoft does not intend custom silicon to eliminate every other accelerator.
Microsoft describes Azure as a heterogeneous AI infrastructure platform combining its own silicon with chips from external suppliers.
That means a cloud provider can use:
Custom accelerator
       +
NVIDIA GPUs
       +
AMD accelerators
       +
Other CPUs / processors
       ↓
Heterogeneous AI infrastructure
This is an important point because the future is unlikely to be simply custom chips versus GPUs.
Large AI infrastructure can use both.
Meta Is Developing MTIA
Meta has also been developing its own AI accelerators under the name MTIA, or Meta Training and Inference Accelerator.
Meta first developed MTIA for its internal AI workloads and has continued expanding the platform.
In March 2026, Meta said it was developing four new generations of MTIA chips over two years for ranking, recommendations and generative AI workloads.
Meta’s MTIA custom silicon strategy
Meta says hundreds of thousands of MTIA chips are deployed for inference workloads across its services.
Meta also announced an expanded partnership with Broadcom to co-develop multiple generations of custom MTIA silicon.
Meta and Broadcom’s custom silicon partnership
This is another example of how custom silicon does not necessarily mean doing every part of chip manufacturing internally.
The company can control the architecture and workload requirements while working with semiconductor specialists for implementation, packaging, networking and manufacturing.
Why Not Just Buy More NVIDIA GPUs?
This is probably the most important question.
If GPUs are already powerful and widely supported, why spend billions developing another type of processor?
There are several reasons.
1. Cost
AI companies operate enormous fleets of accelerators.
Even a small improvement in cost per token can become significant when multiplied across billions or trillions of tokens.
Consider a simplified example:
100 million AI requests
        ×
Small cost reduction per request
        ↓
Large total savings
The larger the workload, the more valuable optimization becomes.
2. Power Efficiency
Electricity is becoming one of the major constraints on AI infrastructure.
AI accelerators consume substantial amounts of power, and the surrounding infrastructure also requires electricity for networking, cooling and storage.
A chip that performs the same workload using less energy can reduce:
- electricity costs
- cooling requirements
- data-center power demand
- infrastructure requirements
Google’s Ironwood announcement specifically highlights power efficiency as a design goal, while Microsoft and Meta have similarly emphasized performance per watt or efficiency in their custom-chip programs.
This is why AI chip design is increasingly connected to data-center design.
3. Better Workload Optimization
A general-purpose accelerator needs to support many different workloads.
A custom chip can focus on a narrower target.
For example:
General GPU

AI training
AI inference
Graphics
Scientific computing
Simulation
Many other workloads


Custom inference accelerator

LLM inference
LLM inference
LLM inference
LLM inference
That specialization can allow engineers to remove or reduce hardware that is not important for the target workload.
The result can potentially be a more efficient system.
4. Memory Matters as Much as Compute
It is easy to look at an AI chip and focus only on its raw compute performance.
But large AI models also require enormous amounts of memory bandwidth.
A processor can be extremely powerful but still spend time waiting for data.
A simplified architecture looks like:
        AI accelerator
             │
       ┌─────┴─────┐
       │ Compute   │
       │ units     │
       └─────┬─────┘
             │
       Memory system
             │
          HBM
             │
       Model weights
If data cannot reach the compute units quickly enough, some of that theoretical compute capability is wasted.
This is why custom AI accelerators pay enormous attention to:
- HBM capacity
- HBM bandwidth
- on-chip SRAM
- cache behavior
- data movement
- inter-chip communication
For more background, our article on how AI chips work explains the basic architecture behind modern AI accelerators.
5. Networking Becomes Critical at Scale
One AI chip is not enough to train or serve the largest models.
Large systems may contain thousands of accelerators.
That means the chips need to communicate with one another.
GPU / AI chip
     │
     ├───────────┐
     │           │
     ↓           ↓
AI chip       AI chip
     │           │
     └─────┬─────┘
           ↓
      High-speed
       network
If communication between accelerators becomes a bottleneck, adding more chips does not necessarily provide proportional performance.
That is why custom AI infrastructure often involves much more than the processor itself.
It includes:
- networking
- switches
- interconnects
- memory
- servers
- racks
- cooling
- software
The chip is one component of the system.
6. Supply and Capacity
There is also a strategic reason for custom silicon.
AI companies need enormous amounts of accelerator capacity.
Depending entirely on external accelerator suppliers can create constraints when demand rises faster than manufacturing capacity.
Developing additional silicon architectures can give large companies another path to increase compute capacity.
However, custom chips do not eliminate semiconductor supply-chain dependencies.
The chips still require:
- advanced manufacturing
- packaging
- HBM
- substrates
- networking components
- fabrication capacity
Companies therefore move control upward in the stack rather than becoming completely independent from semiconductor suppliers.
Custom Chips Do Not Mean Companies Are Abandoning GPUs
This is one of the biggest misconceptions surrounding the custom-chip trend.
The reality is more complicated.
Large AI companies can use multiple types of hardware simultaneously.
For example:
                 AI Infrastructure
                        │
        ┌───────────────┼───────────────┐
        │               │               │
      GPUs        Custom ASICs       CPUs
        │               │               │
   Training        Inference       Coordination
   Research        Serving         Data processing
   General AI      Specific AI     System tasks
Microsoft explicitly describes its Azure infrastructure as heterogeneous, combining its own purpose-built silicon with external hardware.
Meta has similarly said it is taking a portfolio approach and sourcing silicon from multiple industry partners while keeping MTIA as a major part of its infrastructure strategy.
So the future AI data center may contain many different kinds of processors.
Training and Inference May Need Different Chips
Another reason for specialization is that training and inference have different characteristics.
Training involves repeatedly processing huge datasets while updating model parameters.
Training

Dataset
  ↓
Model
  ↓
Compute
  ↓
Update weights
  ↓
Repeat
  ↓
Repeat
  ↓
Repeat
Inference is different.
User request
     ↓
Model
     ↓
Generate tokens
     ↓
Next token
     ↓
Next token
     ↓
Response
Inference may place much greater importance on:
- latency
- cost per token
- memory bandwidth
- serving efficiency
- throughput
- predictable response times
That is why companies such as Google, Microsoft, Meta and OpenAI have all highlighted inference in their custom-chip strategies.
AI Agents Could Make Custom Chips Even More Important
The rise of AI agents adds another dimension.
A traditional chatbot might generate one response.
An agent may perform dozens or hundreds of model calls during a longer workflow.
For example:
User request
     ↓
Reason
     ↓
Search
     ↓
Read documents
     ↓
Write code
     ↓
Run code
     ↓
Inspect result
     ↓
Reason again
     ↓
Make changes
     ↓
Test
     ↓
Final result
Every step can require inference.
Our article on AI agents and how they work explains why this changes the way AI systems consume compute.
If agentic workloads grow substantially, inference efficiency becomes even more important.
Google’s 2026 TPU roadmap explicitly describes TPU 8i as being designed for agentic AI workloads, while OpenAI says its custom accelerator is designed around LLM inference and future agentic products.
The Software Stack Is Just as Important as the Chip
A custom processor is not useful simply because the silicon exists.
Developers need software that can actually use it.
This includes:
- compilers
- kernels
- libraries
- frameworks
- drivers
- scheduling
- monitoring
- debugging tools
The architecture therefore looks like:
AI application
       ↓
AI framework
       ↓
Compiler / runtime
       ↓
Optimized kernels
       ↓
AI accelerator
       ↓
Memory + networking
This is one reason CUDA became so important to NVIDIA’s ecosystem.
A competing chip can have impressive hardware specifications, but developers also need an accessible software stack.
For background, see our article on why NVIDIA CUDA is important for AI computing.
Custom-chip companies therefore have to solve a software problem as well as a semiconductor problem.
The Full-Stack Advantage
The biggest potential advantage of custom silicon appears when a company controls several layers simultaneously.
Consider a simplified stack:
AI Product
     ↓
AI Model
     ↓
Inference Software
     ↓
Compiler / Kernels
     ↓
Chip
     ↓
Server
     ↓
Network
     ↓
Data Center
     ↓
Power + Cooling
A company that operates across many of these layers can optimize them together.
For example:
Model architecture
      ↓
Known memory pattern
      ↓
Custom memory system
      ↓
Optimized chip
      ↓
Optimized networking
      ↓
Optimized data center
That can potentially produce greater efficiency than optimizing every component independently.
This is the logic behind the increasingly full-stack approach to AI infrastructure.
Custom AI Chips Are Also About Data Centers
The chip cannot be separated from the data center anymore.
Modern AI data centers are designed around accelerator clusters, high-bandwidth networking, large power systems and advanced cooling.
Our article on how AI data centers are different from traditional data centers explores this shift.
A custom accelerator may influence:
- rack layout
- power delivery
- cooling
- networking
- server design
- software orchestration
For example:
AI accelerator
      ↓
Server
      ↓
Rack
      ↓
Network
      ↓
Cluster
      ↓
Data center
That means chip architecture can influence the physical architecture of the entire computing facility.
Why AI Companies Cannot Simply Build Everything Themselves
Despite all these advantages, custom silicon is extremely difficult.
Designing a modern AI accelerator requires expertise in:
- semiconductor architecture
- chip design
- verification
- packaging
- memory
- networking
- manufacturing
- compilers
- operating systems
- distributed computing
And the costs can be enormous.
This is why many AI companies collaborate with established semiconductor companies.
OpenAI is working with Broadcom on Jalapeño.
Meta is working with Broadcom on multiple generations of MTIA.
Other companies work with foundries, packaging providers, memory manufacturers and networking companies.
The modern custom-chip model therefore looks more like:
AI company
    +
Chip designer
    +
Foundry
    +
HBM supplier
    +
Networking company
    +
System integrator
It is an ecosystem rather than a single company doing everything.
The Economics of Custom Silicon
The economics become particularly interesting at very large scale.
Suppose a company operates:
10,000 accelerators
A small improvement in:
- power consumption
- utilization
- memory efficiency
- performance per dollar
- network efficiency
can produce a significant difference across the entire fleet.
Now imagine:
100,000 accelerators
or more.
The optimization becomes much more valuable.
This creates an important threshold:
Small AI workload
        ↓
Buy general-purpose accelerator


Huge AI workload
        ↓
Optimization becomes extremely valuable
        ↓
Custom silicon becomes more attractive
That does not mean custom chips are always cheaper.
The engineering cost has to be justified by enough volume and workload consistency.
The Biggest Challenge: AI Changes Very Quickly
There is also a major risk.
AI architectures evolve rapidly.
A chip designed around today’s models may not be ideal for tomorrow’s models.
For example:
Chip design
    ↓
Manufacturing
    ↓
Deployment
    ↓
AI architecture changes
    ↓
Workload changes
    ↓
New chip required
That makes flexibility extremely important.
Meta says its MTIA strategy uses modular designs and rapid development cycles partly so it can respond more quickly to changing AI workloads.
Google is also developing different TPU generations and specialized chips for different workload requirements.
The challenge is therefore not simply designing a powerful chip.
It is designing one that remains useful as AI changes.
Why This Does Not Mean NVIDIA Is No Longer Important
The growth of custom AI chips does not automatically mean the end of NVIDIA’s role.
NVIDIA GPUs remain important because they offer a combination of:
- mature hardware
- large-scale availability
- CUDA software
- developer adoption
- networking
- AI libraries
- broad workload support
Custom accelerators are competing on a different dimension.
They can be optimized around specific workloads and infrastructure.
The industry can therefore evolve toward:
NVIDIA GPUs
      +
AMD accelerators
      +
Google TPUs
      +
Amazon Trainium
      +
Microsoft Maia
      +
Meta MTIA
      +
Other custom accelerators
Instead of one processor architecture controlling every AI workload, the industry may increasingly use a portfolio of accelerators.
The Future May Be a Heterogeneous AI Data Center
The most important long-term trend may therefore be heterogeneous computing.
A future AI data center could contain different processors for different jobs.
                 AI Data Center
                       │
       ┌───────────────┼───────────────┐
       │               │               │
   Training         Inference       General CPU
       │               │               │
      GPU         Custom ASIC          CPU
       │               │               │
   Research        AI serving      Data / agents
One workload may favor a GPU.
Another may favor a custom inference accelerator.
Another may require a CPU.
The software layer will increasingly decide which hardware should execute which task.
What This Means for the AI Industry
The custom-chip movement is changing the economics of AI infrastructure.
The competition is no longer only:
Who can build the best AI model?
It is also:
Who can run that model most efficiently at enormous scale?
That requires optimization across multiple layers:
Better models
     ↓
Better algorithms
     ↓
Better inference
     ↓
Better chips
     ↓
Better networking
     ↓
Better cooling
     ↓
Better data centers
     ↓
Lower cost per AI operation
This is why companies that originally focused on software and AI models are increasingly becoming involved in semiconductor architecture.
Why AI Companies Are Building Their Own Chips
The answer ultimately comes down to control and optimization.
AI companies want more control over:
- compute costs
- inference performance
- power consumption
- memory architecture
- networking
- hardware availability
- data-center efficiency
- software-hardware integration
But custom silicon is not a replacement for every external accelerator.
The more likely future is a combination of general-purpose GPUs, specialized AI accelerators and CPUs working together.
The AI infrastructure stack could increasingly look like this:
                AI Applications
                       ↓
                  AI Models
                       ↓
              AI Agent Systems
                       ↓
             Software / Compilers
                       ↓
        ┌──────────────┼──────────────┐
        ↓              ↓              ↓
      GPUs       Custom AI Chips     CPUs
        ↓              ↓              ↓
        └──────────────┼──────────────┘
                       ↓
                 High-Speed Network
                       ↓
                AI Data Center
                       ↓
                Power + Cooling
The interesting part of the AI chip race is therefore not simply which company produces the fastest processor.
It is the shift toward hardware designed together with models, software and data-center infrastructure.
As AI inference grows and AI agents perform longer and more complex workflows, the economics of every token become more important.
That makes specialized silicon one of the most important pieces of the next phase of AI infrastructure.

SiliconeUpdate.com is a technology news platform that publishes updates and informational content related to silicon technology, software, artificial intelligence, and emerging technologies.
All articles published on this platform are attributed to SiliconeUpdate.com instead of individual authors. Content is presented in a neutral, informational format without personal opinions.
—
Content Publishing
SiliconeUpdate.com publishes news and updates based on publicly available information, official announcements, and industry developments. The focus is on clarity, relevance, and timely reporting.
—
Editorial Control
All editorial decisions, updates, and content management are handled at the platform level. No individual human or AI identity is presented as the author of articles.
—
Contact
For editorial communication or general queries, contact:
Email: neemasharma@gmail.com